


Dense Layouts & Readable Text
Fit long prompts, exact copy, multiple panels, and structured information into one image.
Year's Biggest Deal: 439k+ credits for $1999 (+120% Bonus) - Ends Sep 30.
View all offers
You have free credits!
Create your first AI video right away.
Qwen-Image-3.0 is now live on Pixmax. Bring more detail into every image with 4,500-token prompts, multilingual text rendering, realistic textures, and precise image editing.
Create with Qwen-Image-3.0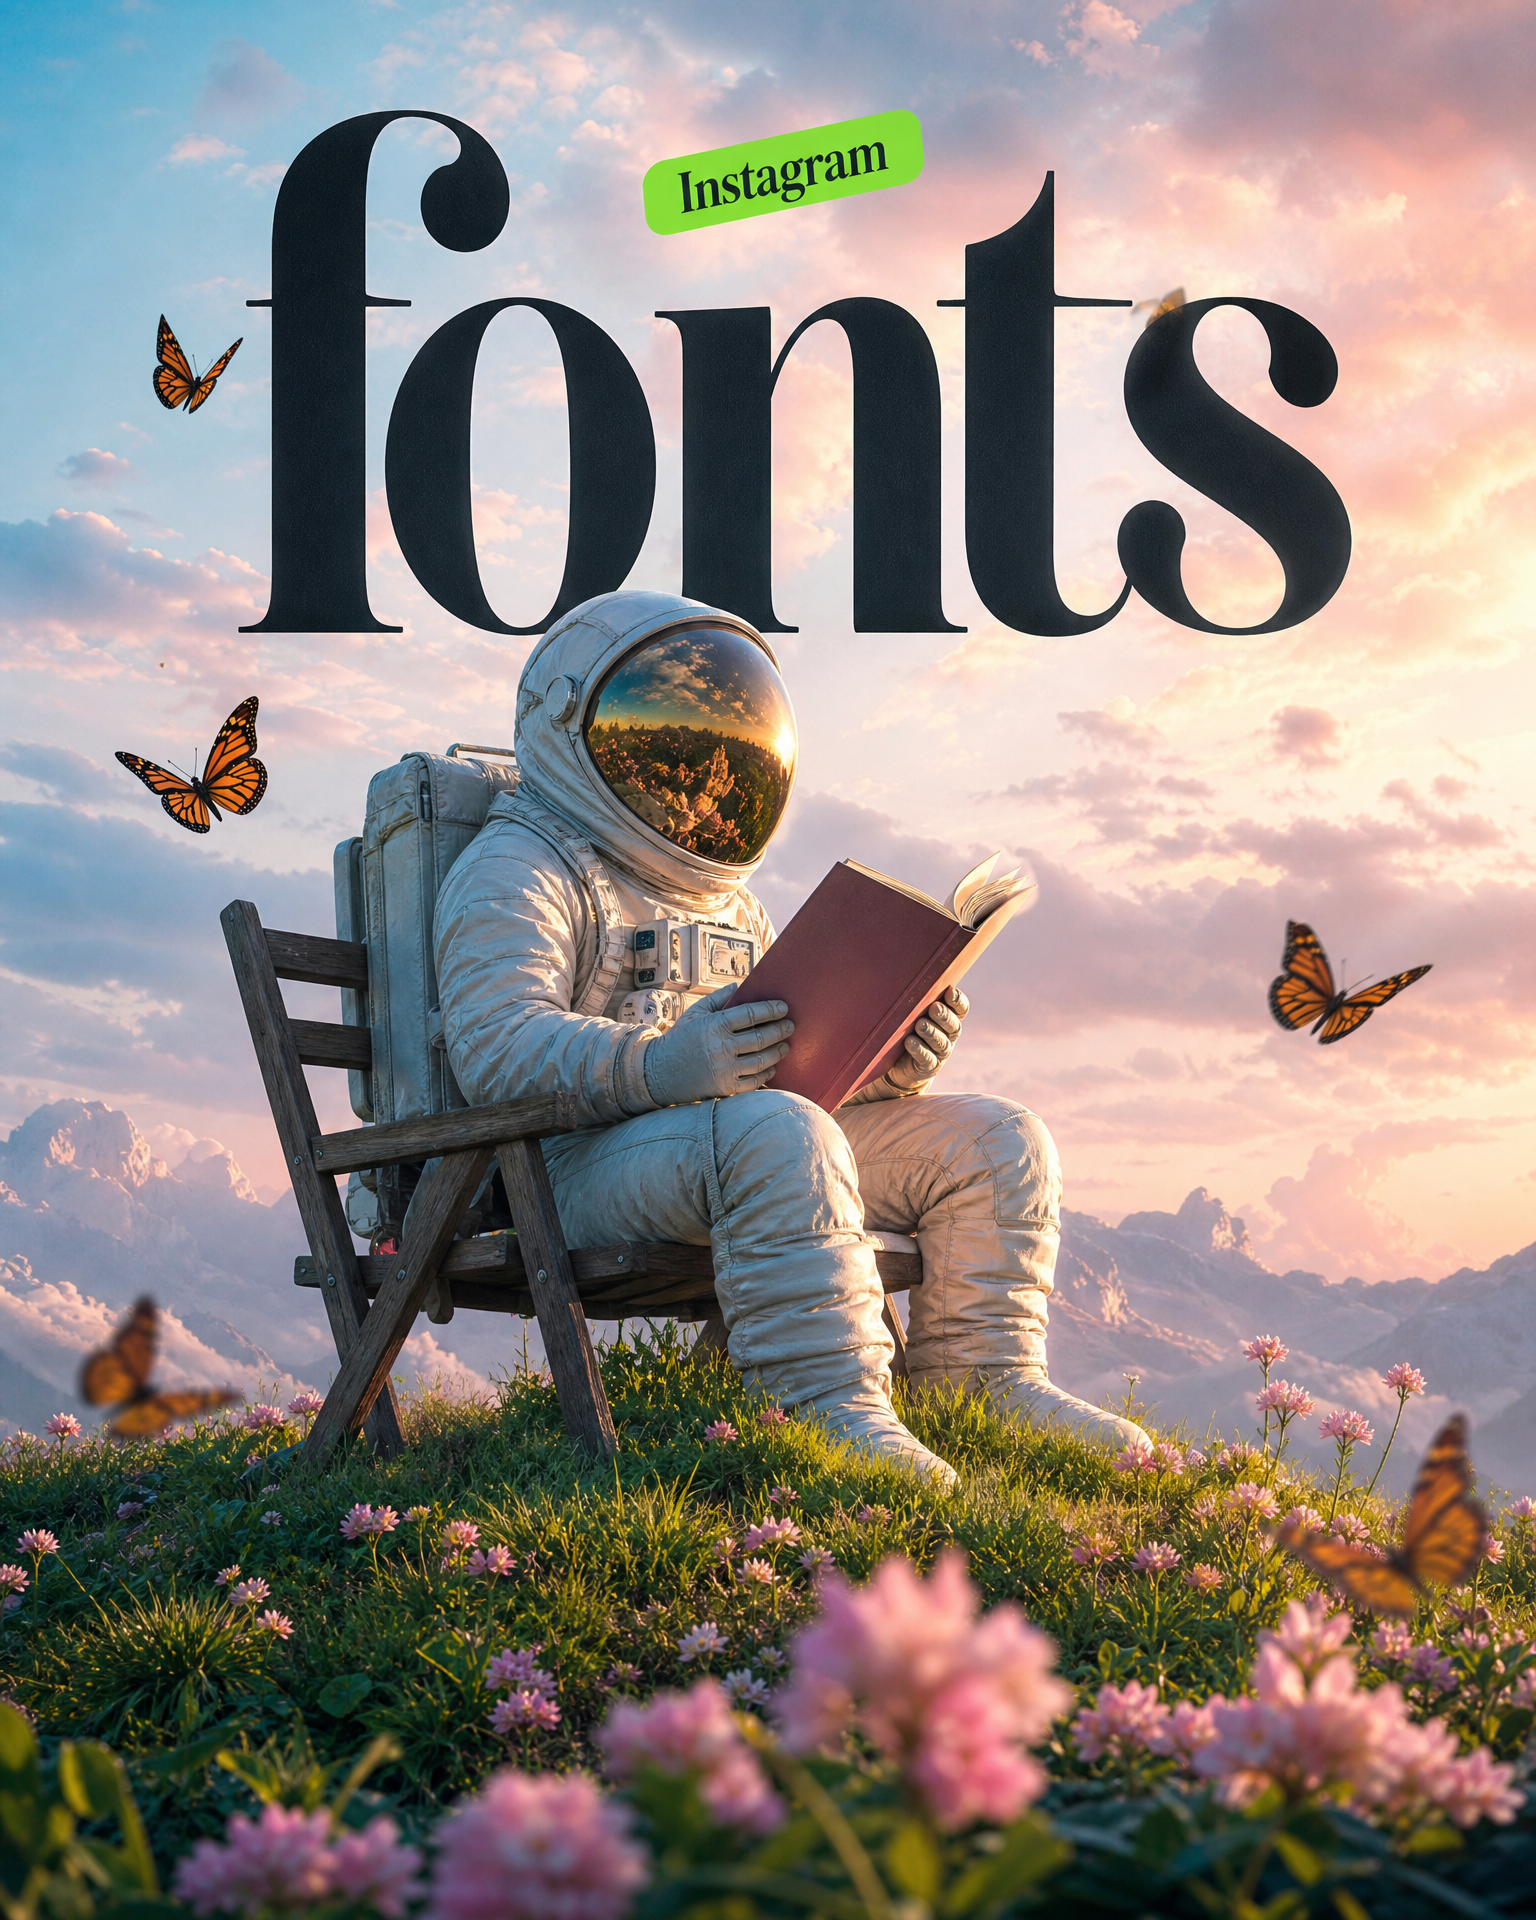
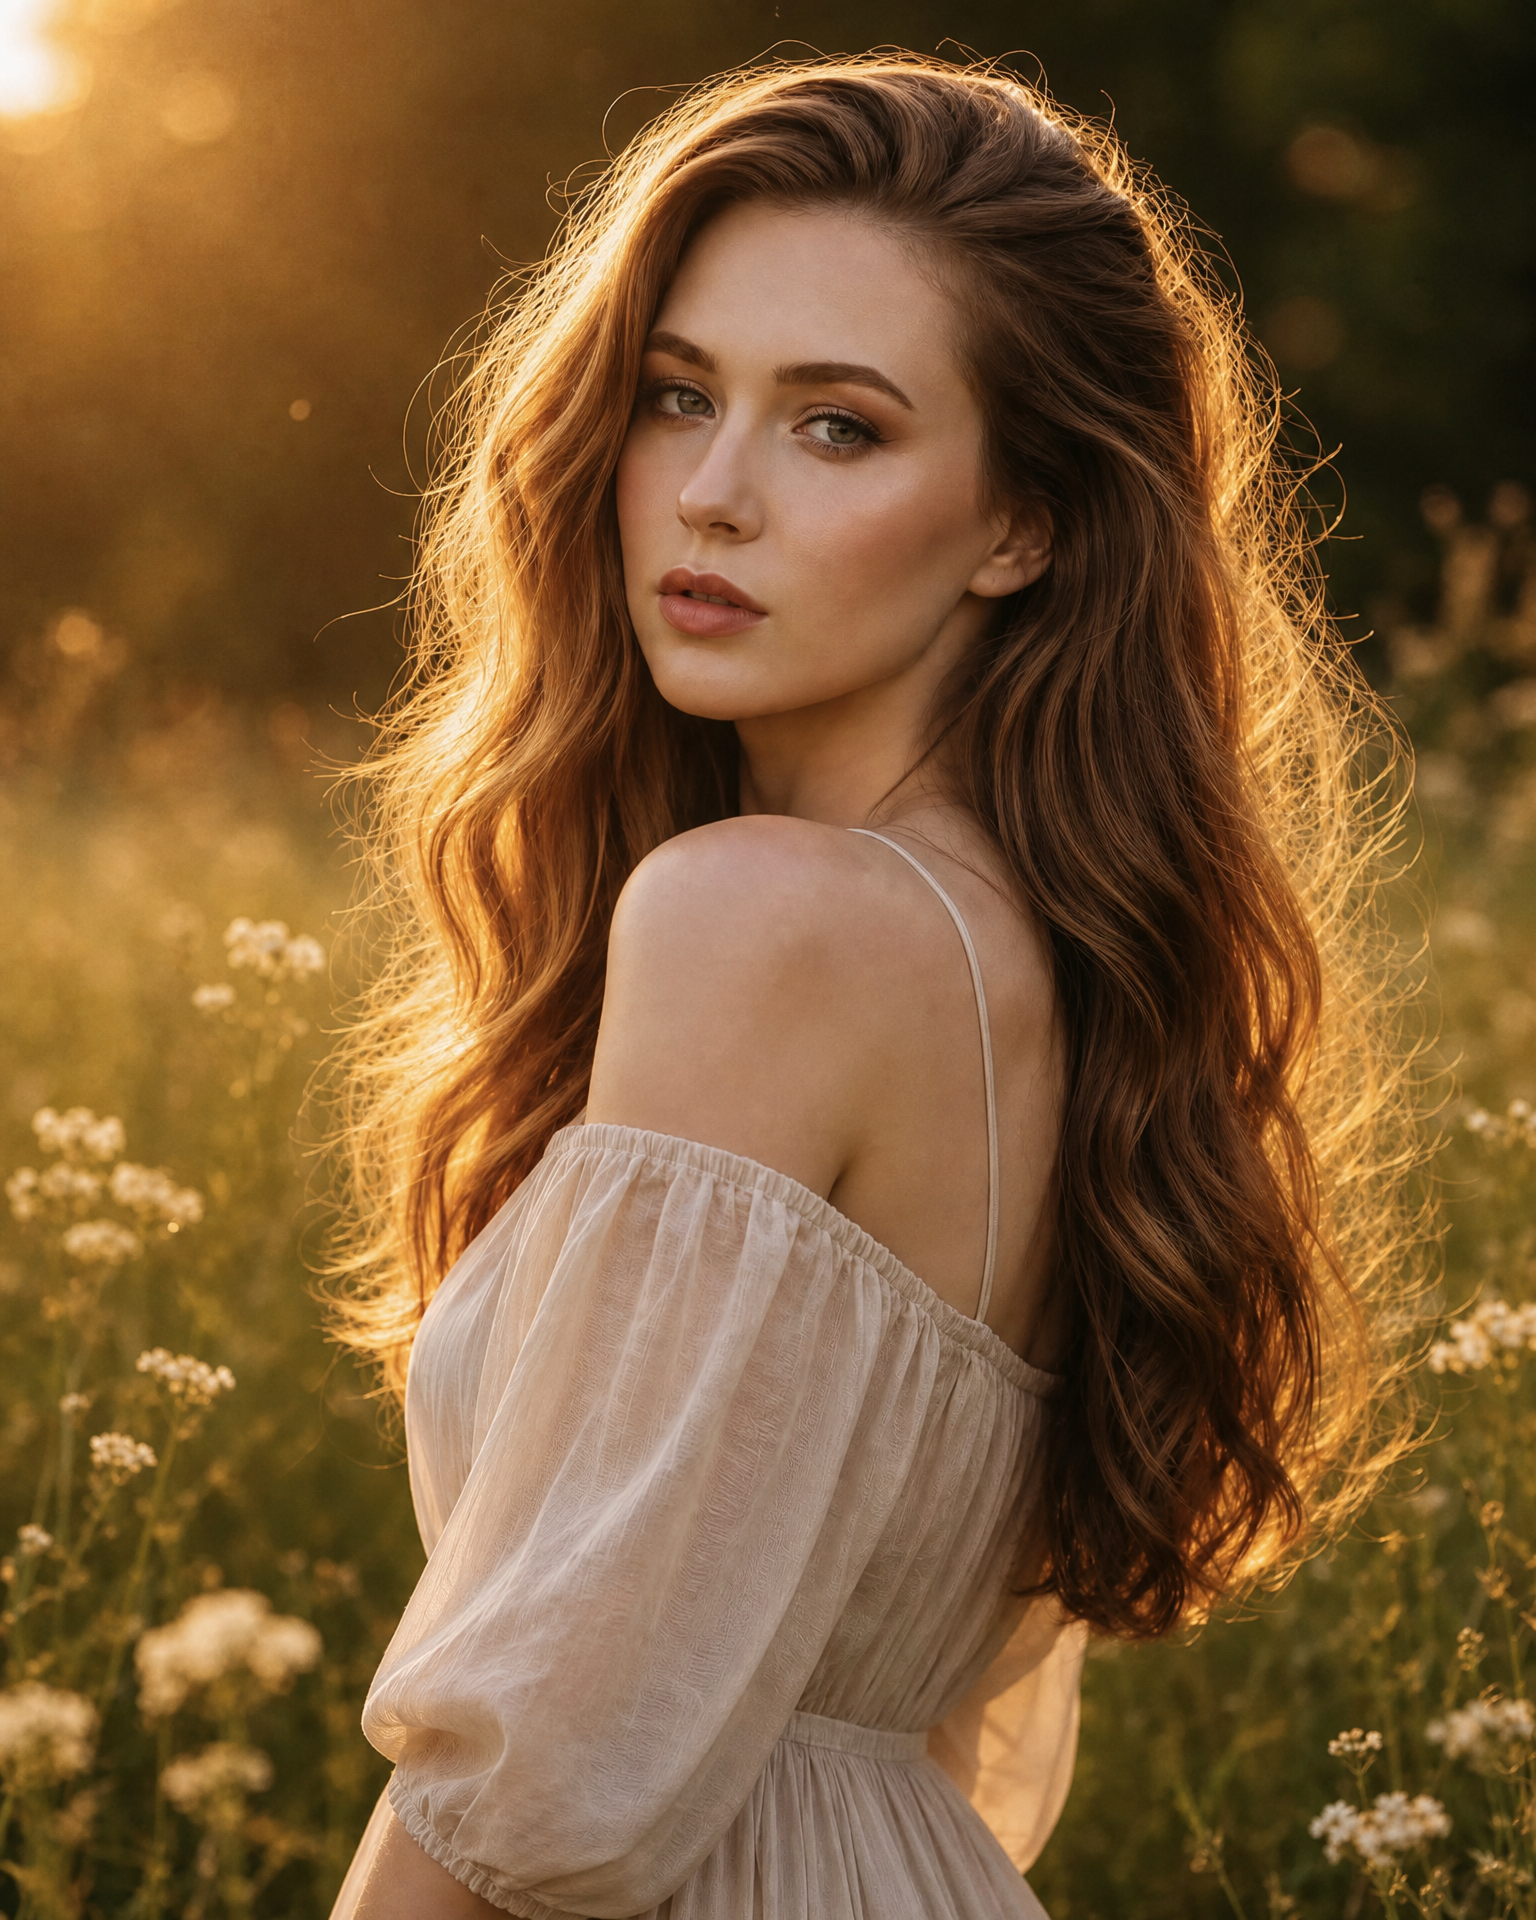
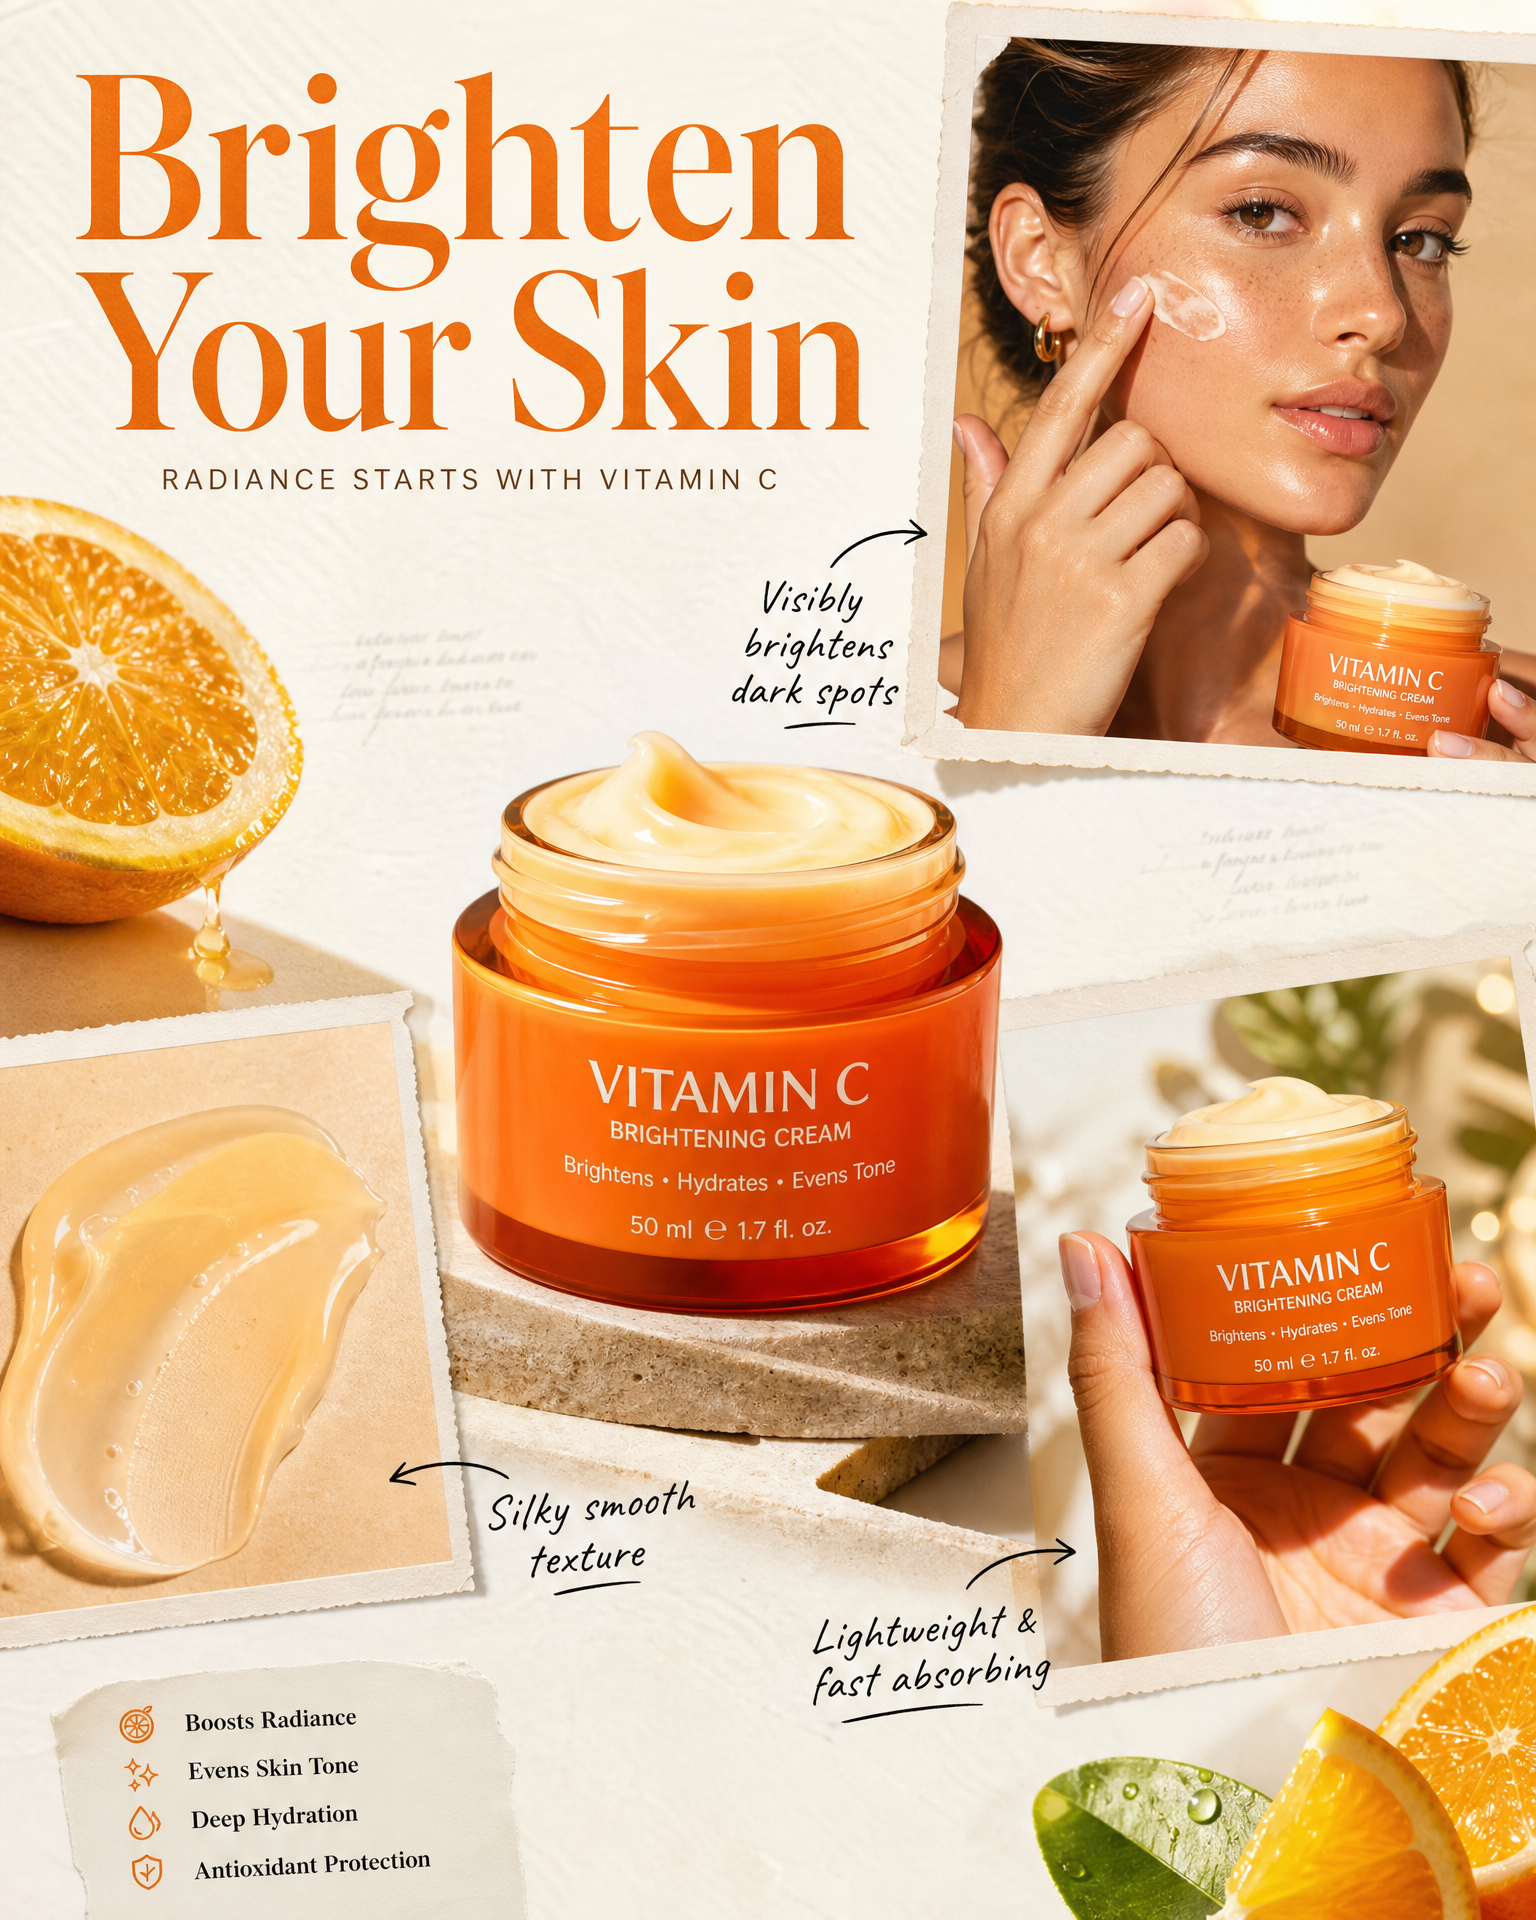
Fit long prompts, exact copy, multiple panels, and structured information into one image.
Create posters, infographics, UI concepts, and packaging with native text in 12 languages.
Preserve identity and key details while adding annotations, restoring artwork, or changing a scene.
GENERATION & IMAGE EDITING
Use reference images and natural-language instructions to change a scene while preserving important visual details.
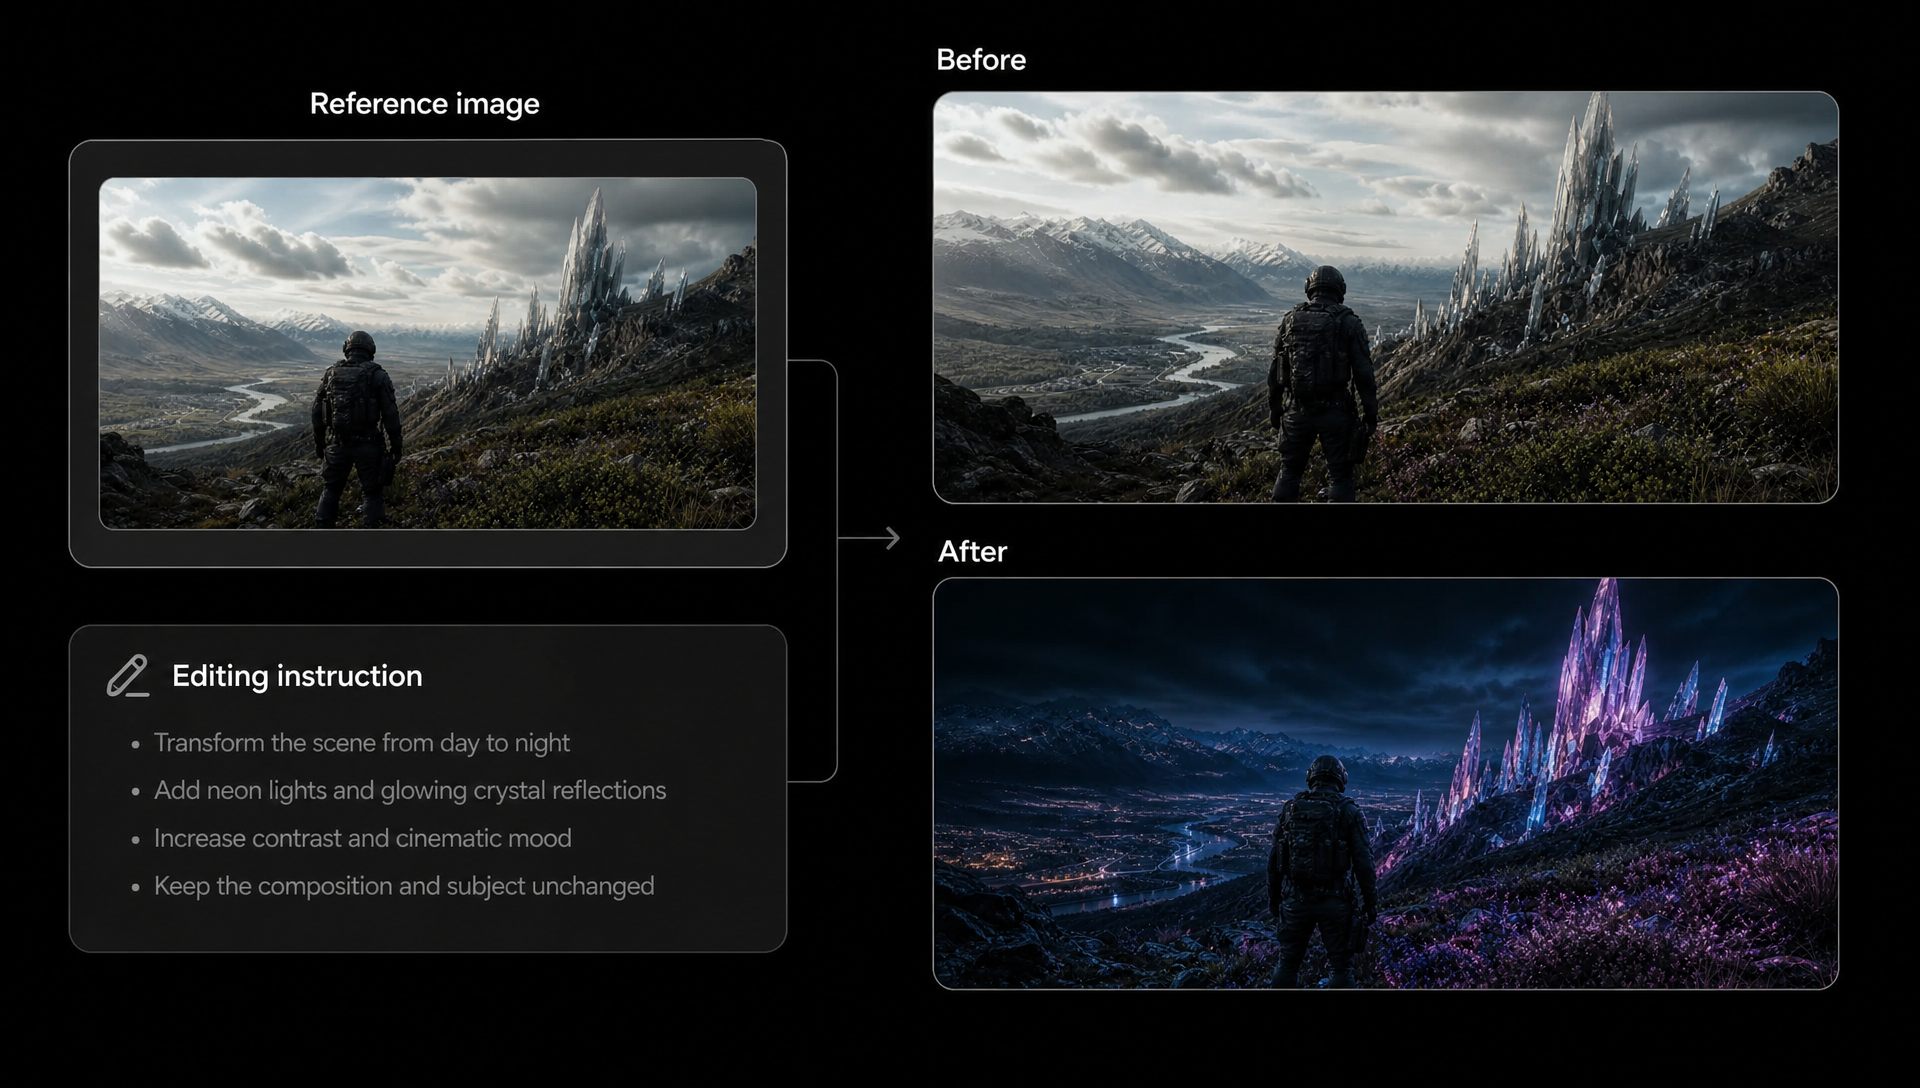
Use final outputs here. Keep prompts and reference notes as additions for content review and design handoff.
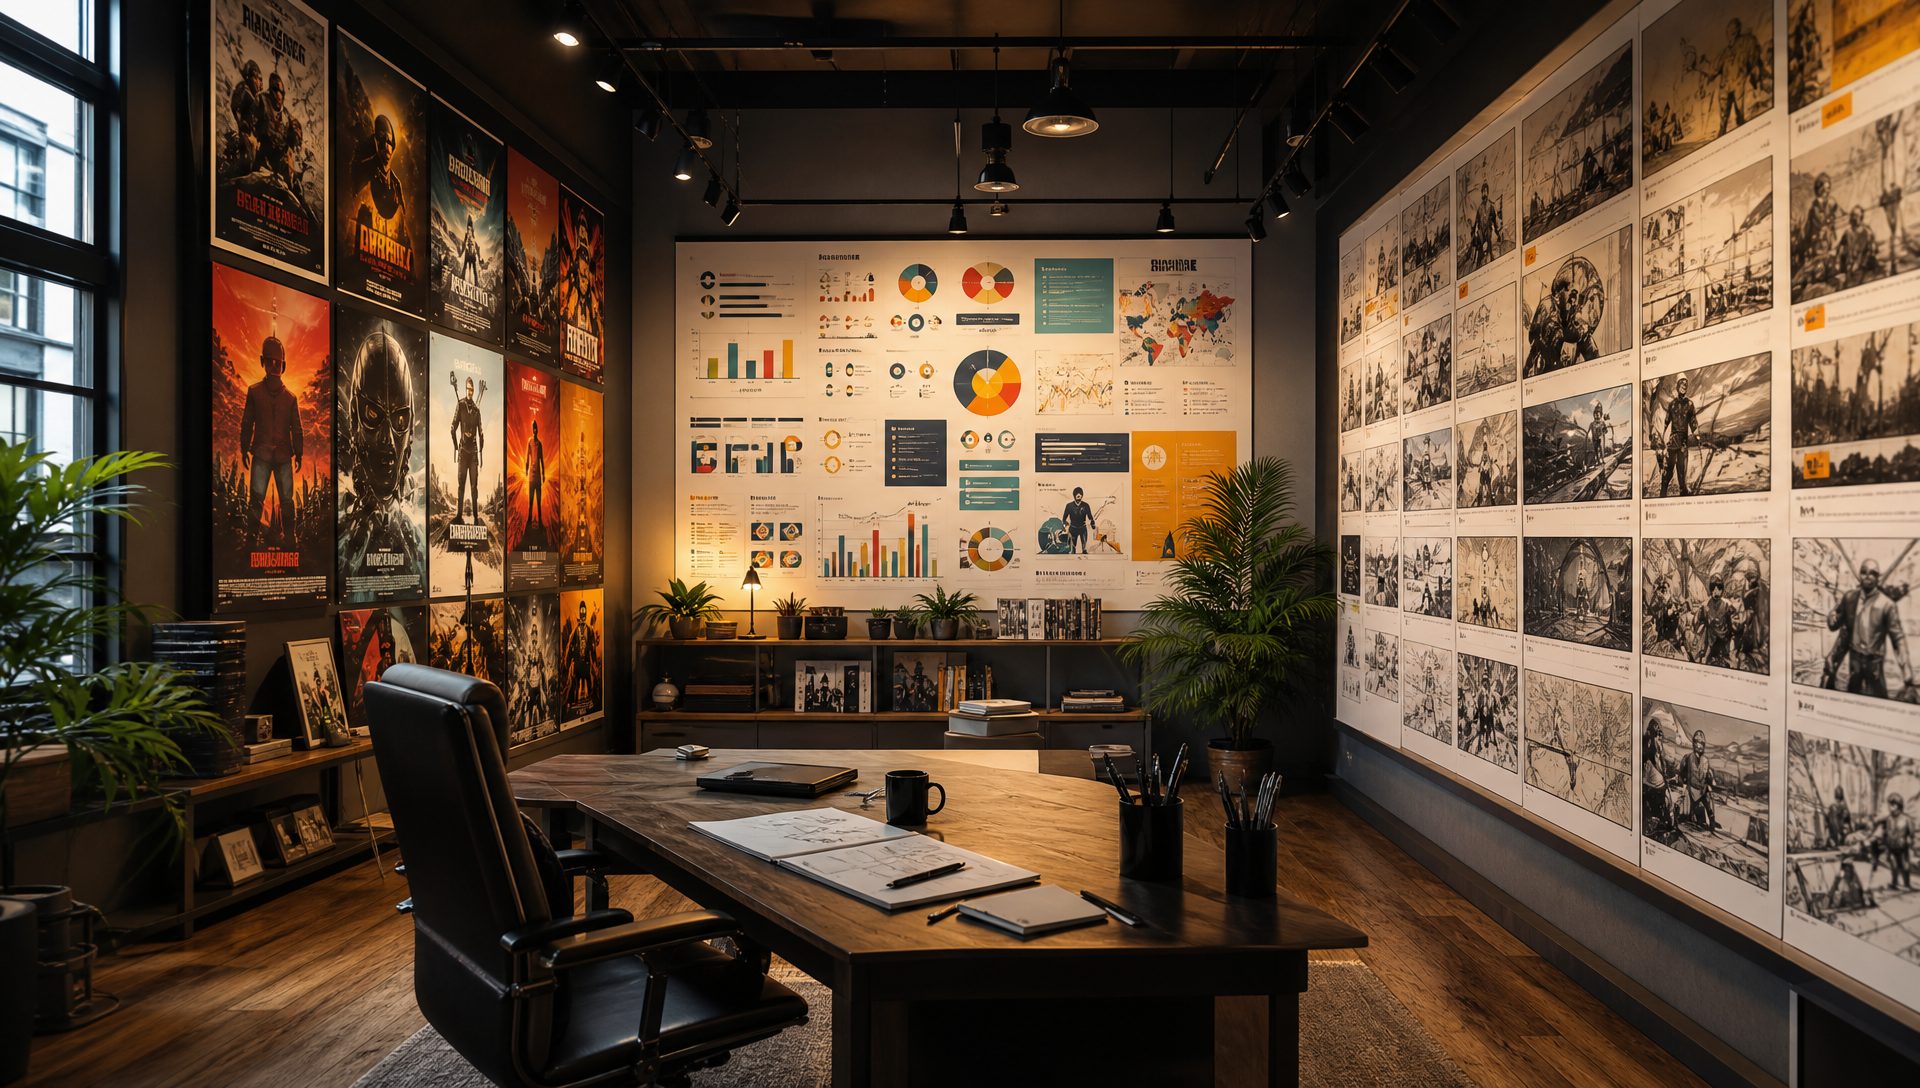
Choose Qwen when the image must explain, label, compare, or tell a multi-panel story.
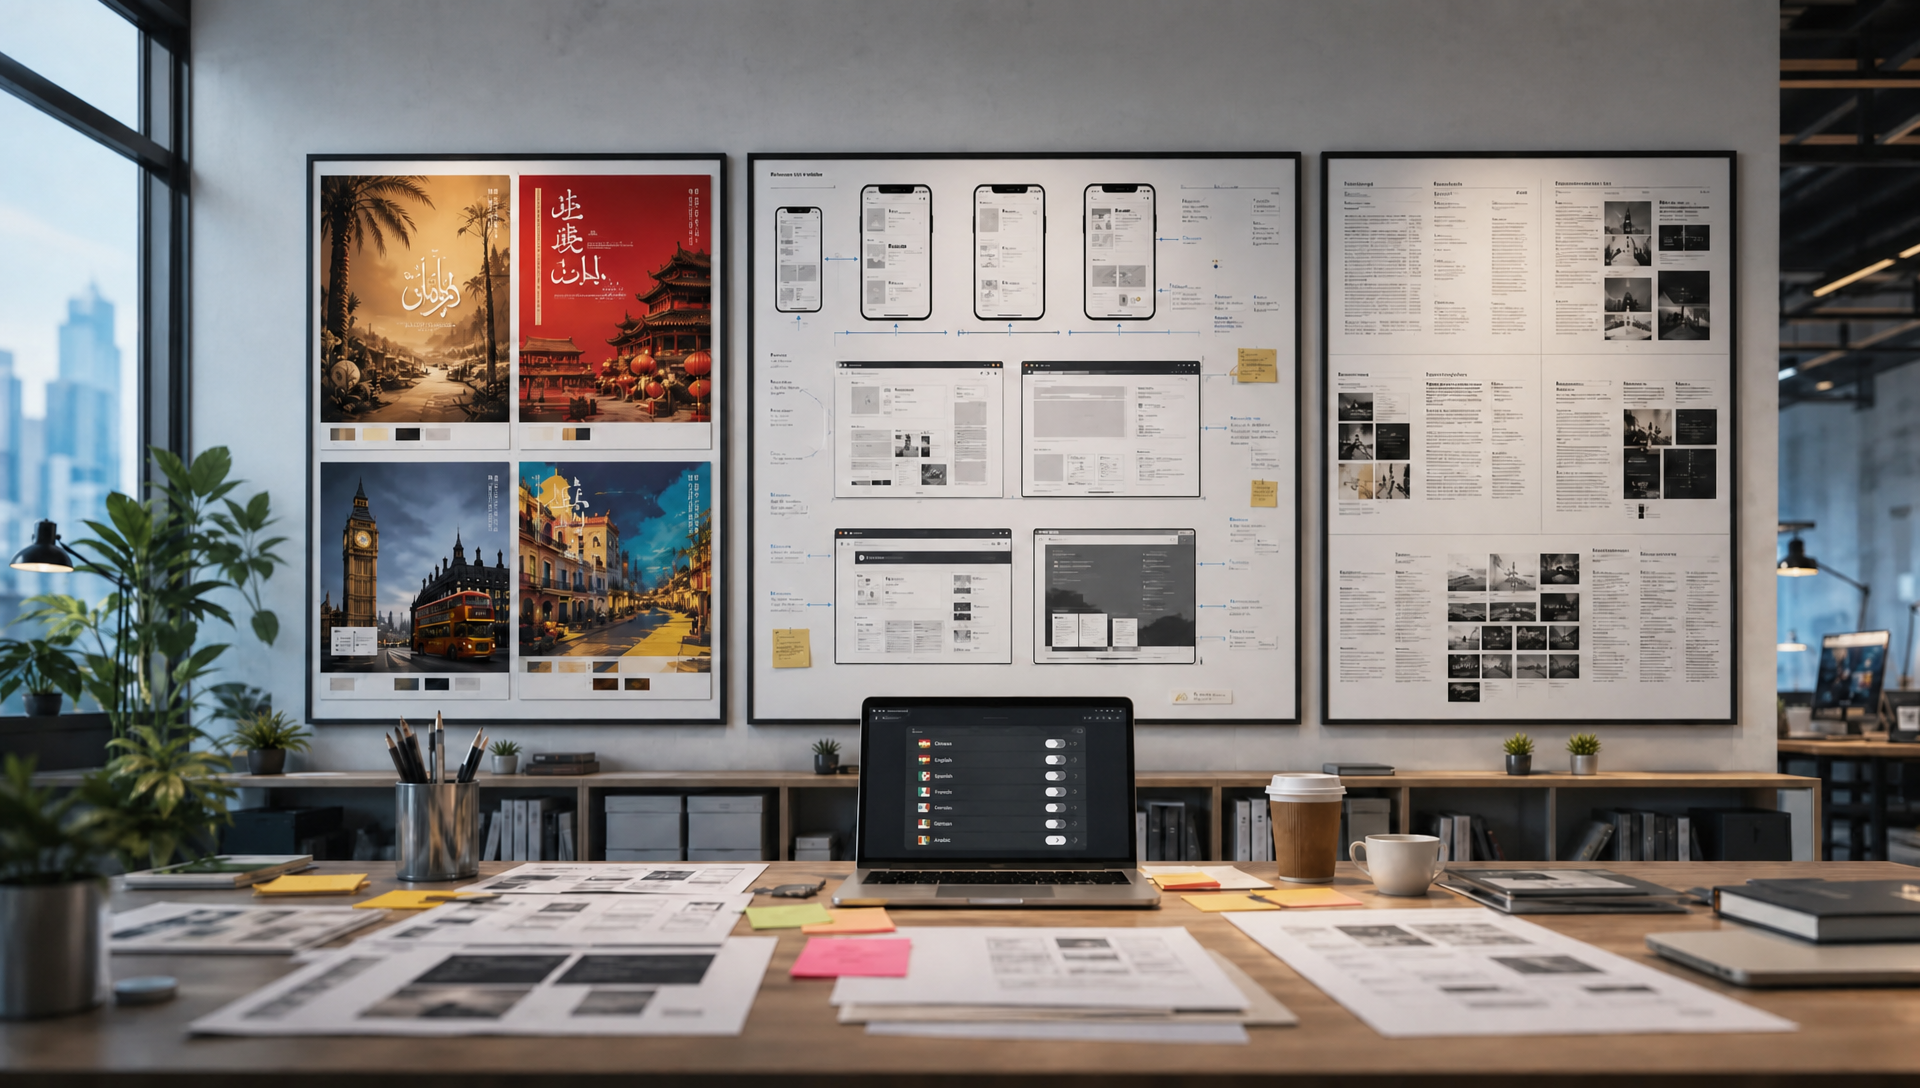
Use it for localized campaign visuals, readable interface drafts, and text-heavy layouts.
Choose a video model when motion, temporal consistency, or animation is the primary output.
| Model type | Text-to-image and image editing |
|---|---|
| Core edge | Dense layouts, readable text, and realistic detail |
| Prompt length | Up to 4,500 tokens |
| Text rendering | 12 languages, 20+ fonts, ~10px examples |
| Editing input | One to three reference images |
| Output resolution | Up to 2048 × 2048 |
| Best for | Information-rich visuals and controlled edits |
| Compared with general models | Prefer Qwen for text-heavy layouts; choose style-first models for open-ended aesthetics |
Pixmax also brings together leading AI models for video, image, voice, and creative production, supporting AI shorts, ad videos, product showcases, and social content workflows.
It is strongest at information-rich images: dense layouts, readable text, multilingual visuals, realistic detail, and controlled edits.
Choose Qwen when text accuracy, long prompts, structured composition, or reference-image editing matter more than purely style-first exploration.
The model supports instructions up to 4,500 tokens, so you can describe layout, exact text, style, objects, and fine details in one prompt.
Yes. It supports one to three reference images with natural-language instructions for preserving identity, adding annotations, restoring artwork, or changing a scene.
Create rich layouts, multilingual visuals, and realistic imagery with Qwen-Image-3.0.

